Building a Governed AI & Data Intelligence Platform with Microsoft Fabric
A Fabric and AI data platform unifies enterprise data and documents, enabling governed RAG, analytics, and permission-aware AI experiences.
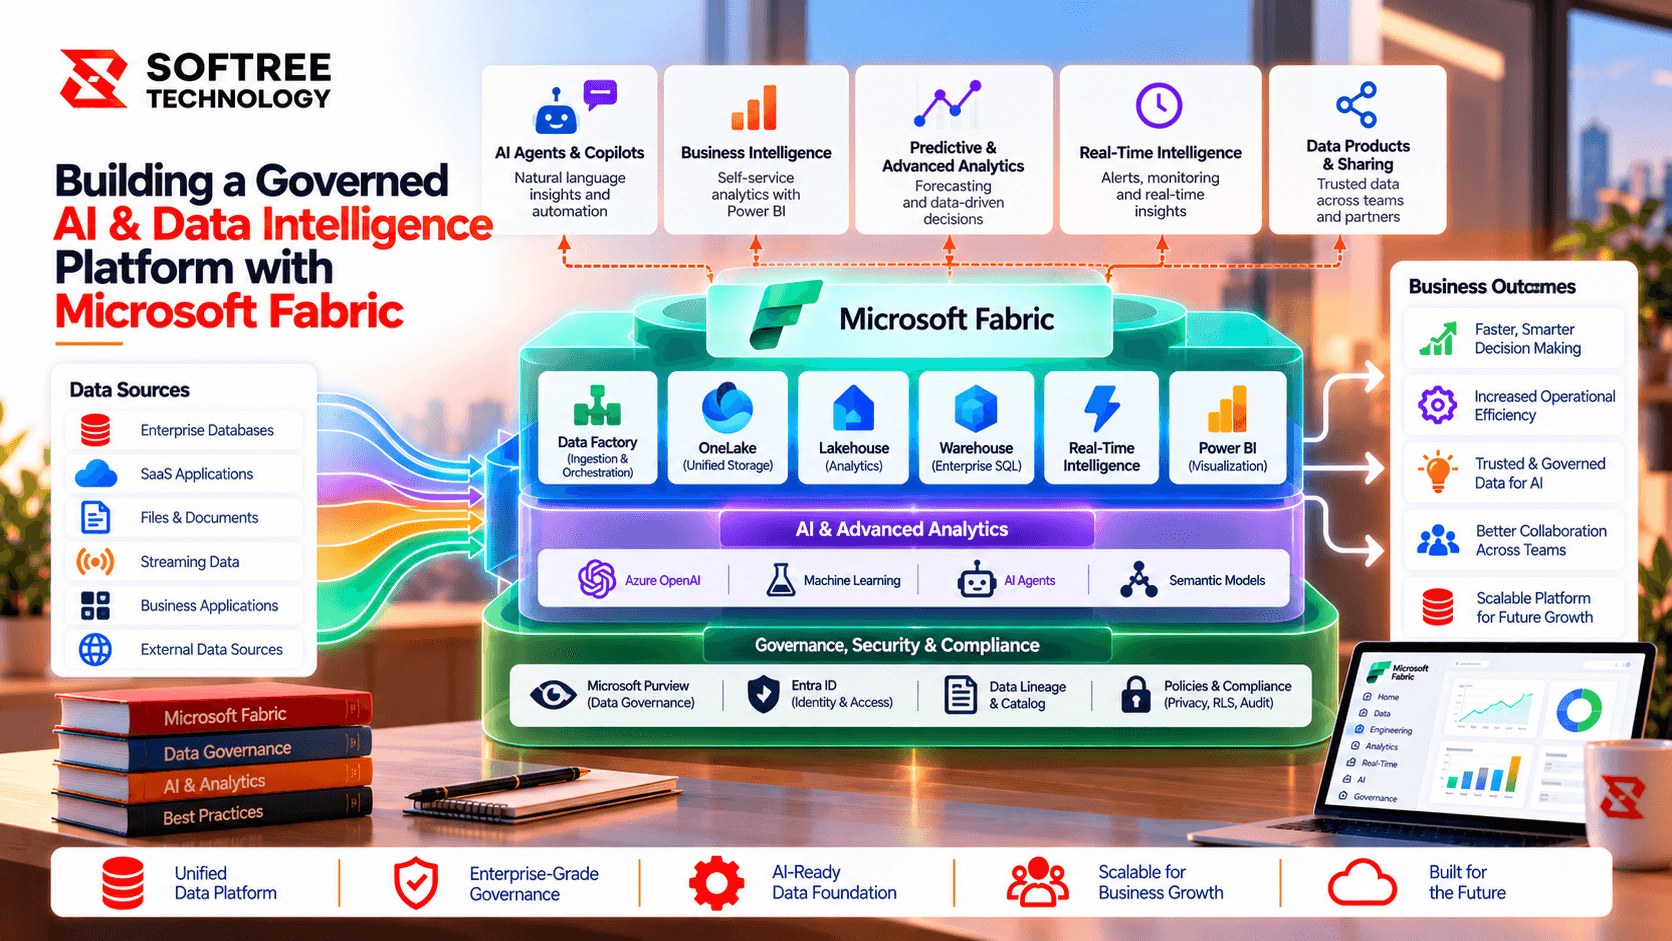
Business Process Challenges
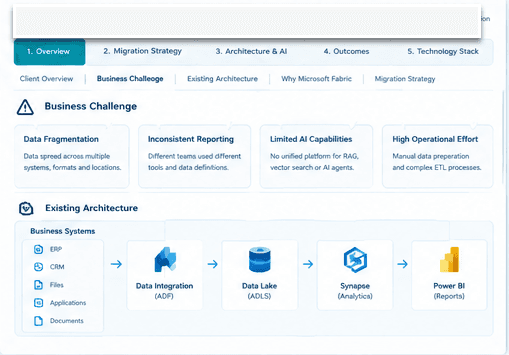
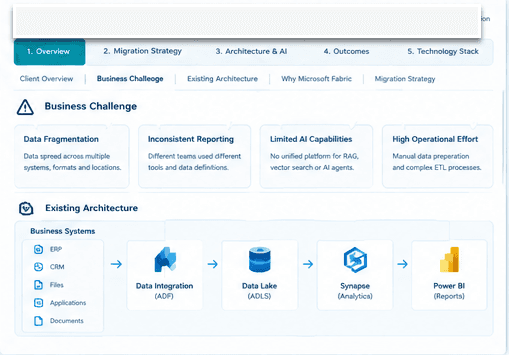
Enterprise data was distributed across business applications, operational databases, SaaS platforms, Azure Data Factory pipelines, Azure Synapse workloads, Power BI models, and document repositories. This fragmentation made it difficult to maintain consistent data definitions, reuse integration logic, and establish clear ownership and lineage. Employees also struggled to find information across documents, policies, contracts, technical content, and analytical data, while traditional dashboards were limited in their ability to support natural-language discovery.
Key challenges included:
- Fragmented data: Multiple systems and repositories created disconnected information sources.
- Duplicated integration: Repeated pipelines and data preparation increased maintenance effort.
- Inconsistent definitions: Different semantic models could produce conflicting business metrics.
- Limited data visibility: Ownership, lineage, and governance were difficult to track.
- Restricted information discovery: Users needed a better way to search across structured and unstructured data.
- AI governance requirements: Enterprise AI needed permission enforcement, relevant retrieval context, source references, evaluation, monitoring, and controlled agent actions.
Our Strategic Approach
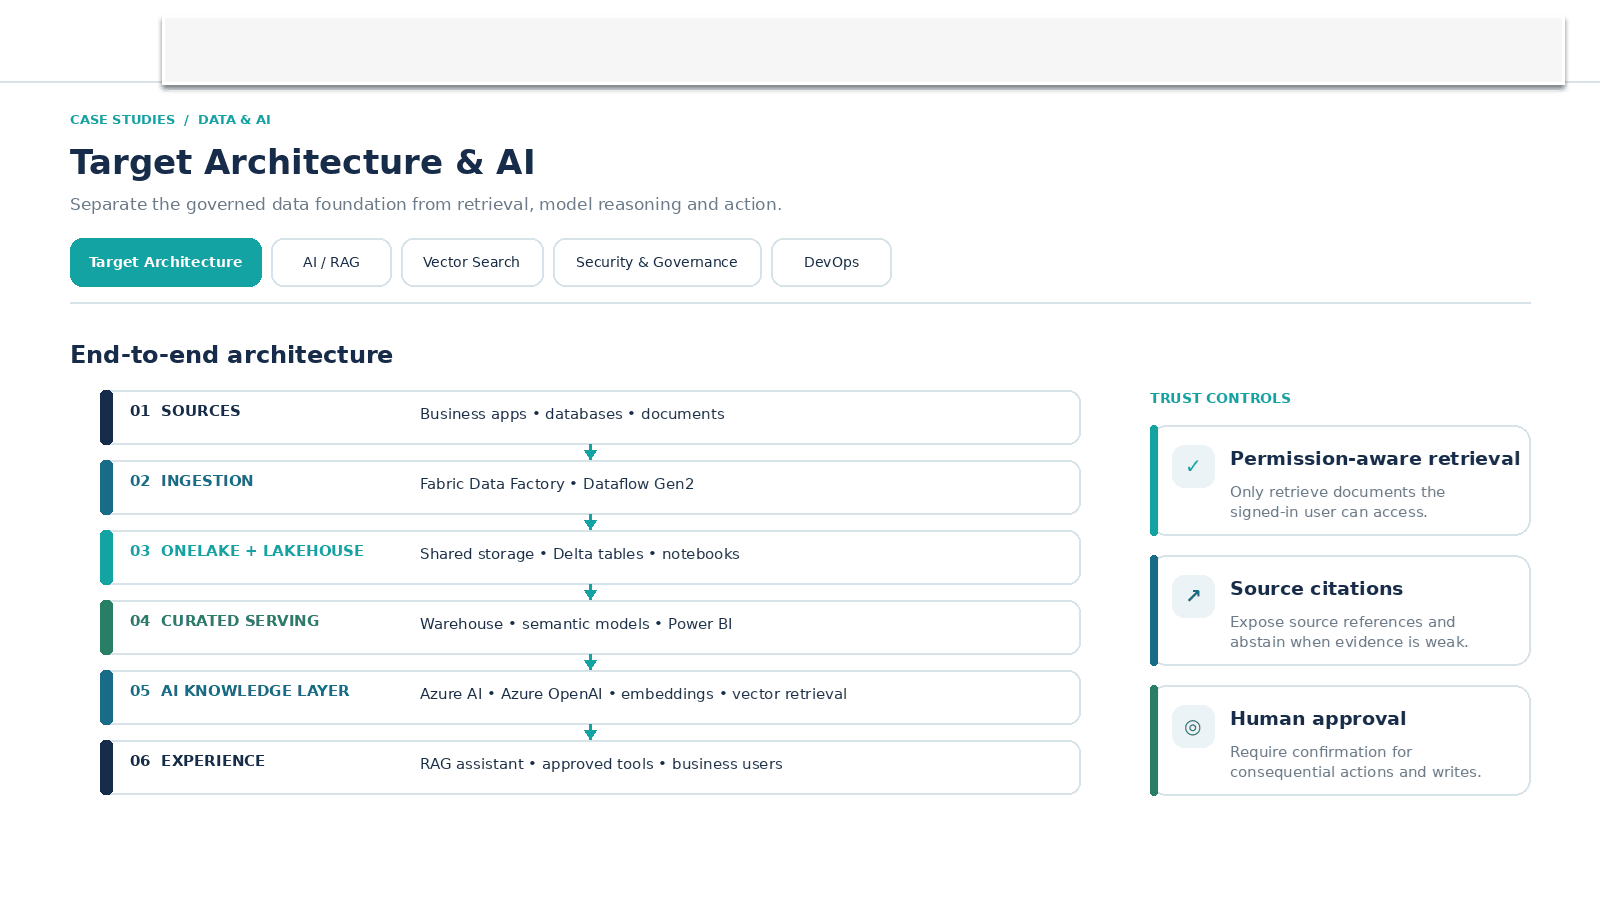
Softree designed a governed Microsoft Fabric + Azure AI / Azure OpenAI architecture that separates the enterprise data foundation from the AI retrieval and reasoning layer. Fabric provides the foundation for ingestion, OneLake storage, Lakehouse engineering, Warehouse serving, semantic models, and analytics.
The approach follows a phased modernization model:
- Discovery: Inventory ADF pipelines, Synapse workloads, Power BI assets, source systems, dependencies, SLAs, and security requirements.
- Fabric Foundation: Establish OneLake, Lakehouse patterns, workspace strategy, identity, governance, monitoring, and deployment controls.
- Data Engineering: Migrate or refactor suitable pipelines and build curated data products using Fabric Data Factory, Dataflow Gen2, Notebooks, Spark/PySpark, and SQL.
- Analytics Modernization: Consolidate semantic models, standardize business measures, validate RLS, and modernize Power BI reporting.
- AI & RAG: Prepare approved documents, generate embeddings, apply hybrid retrieval and permission filters, and ground Azure OpenAI responses in authorized context.
- Governance & Security: Apply least-privilege access, lineage, metadata, retrieval-time authorization, monitoring, evaluation, and audit controls.
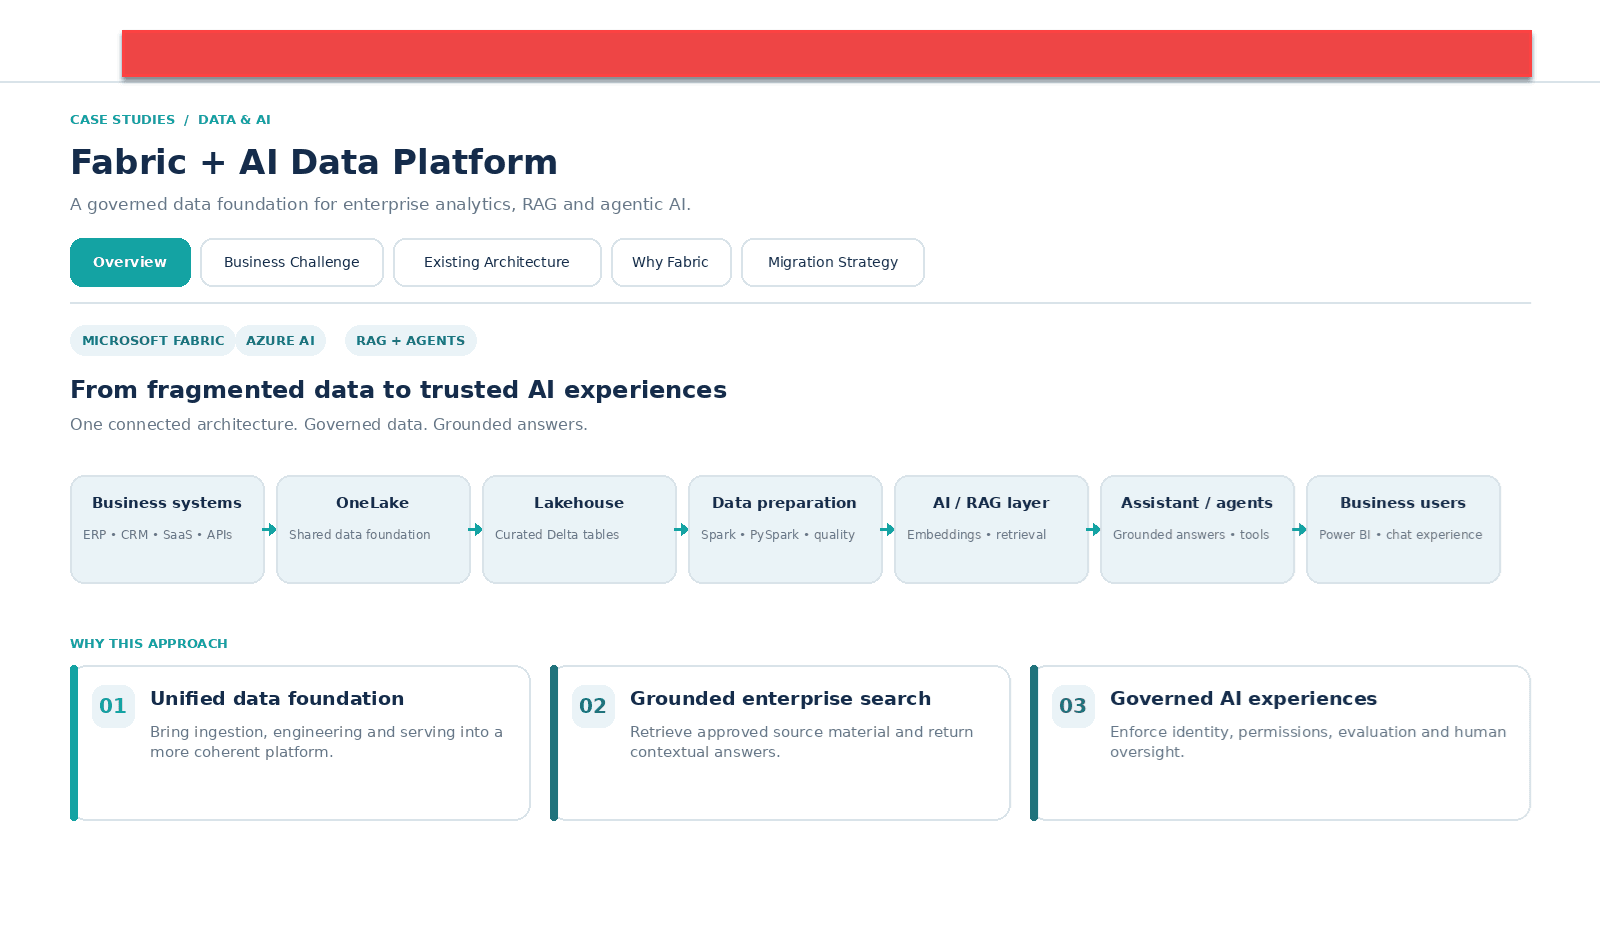
The target architecture follows:
Business Systems → Fabric Data Factory → OneLake → Lakehouse → Curated Data → AI/RAG → AI Assistants → Business Users
Our Engineering & Delivery Process
Our structured project delivery approach takes you from discovery and planning to development, testing, and deployment, ensuring quality, transparency, and predictable outcomes at every stage.
Discovery & Architecture
Deep-dive technical audit of existing systems, security baselines, API mapping, and comprehensive cloud target blueprinting.
UX & System Prototyping
Role-based user journeys, wireframing, high-fidelity clickable Figma prototypes, and API contract specifications prior to build.
Agile Sprint Engineering
Modular development sprints delivering clean, shippable code with automated CI/CD pipelines and continuous testing.
QA & Security Hardening
End-to-end regression suites, cross-device verification, load stress audits, and penetration testing for enterprise resilience.
Production Launch & Scale
Zero-downtime blue-green production deployment, real-time telemetry, administrator training runbooks, and ongoing SLA support.
Explore the Solution Through visuals
What changed for the client.
Because this is an illustrative scenario, no measured customer results are claimed. The proposed architecture is designed to deliver measurable improvements that can be validated during implementation.
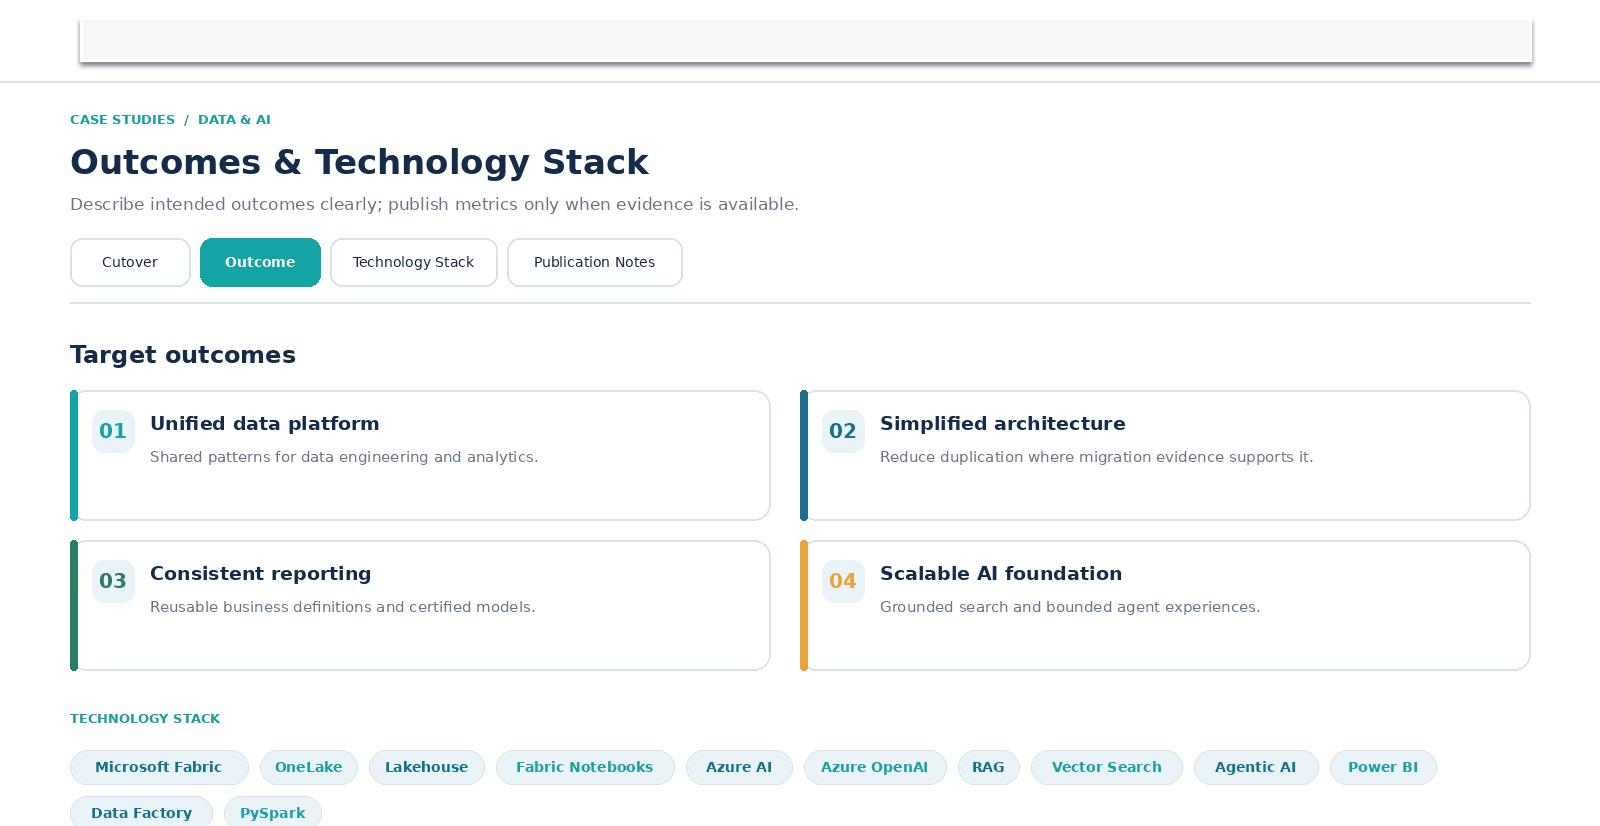
Expected outcomes include:
- A more unified and governed enterprise data foundation
- Reusable ingestion and transformation patterns
- More consistent business definitions and reduced reporting duplication
- Faster discovery of approved enterprise information
- AI responses grounded in permitted sources with citations where supported
- Stronger deployment, monitoring, access, and rollback controls
- A scalable foundation for additional analytics and AI use cases
Softree recommends establishing baselines for pipeline performance, refresh duration, report usage, manual search effort, data quality, AI retrieval quality, and operational metrics before publishing quantitative improvements.
The numbers behind the rollout.
The full integration layer.
Other engagements worth a look.
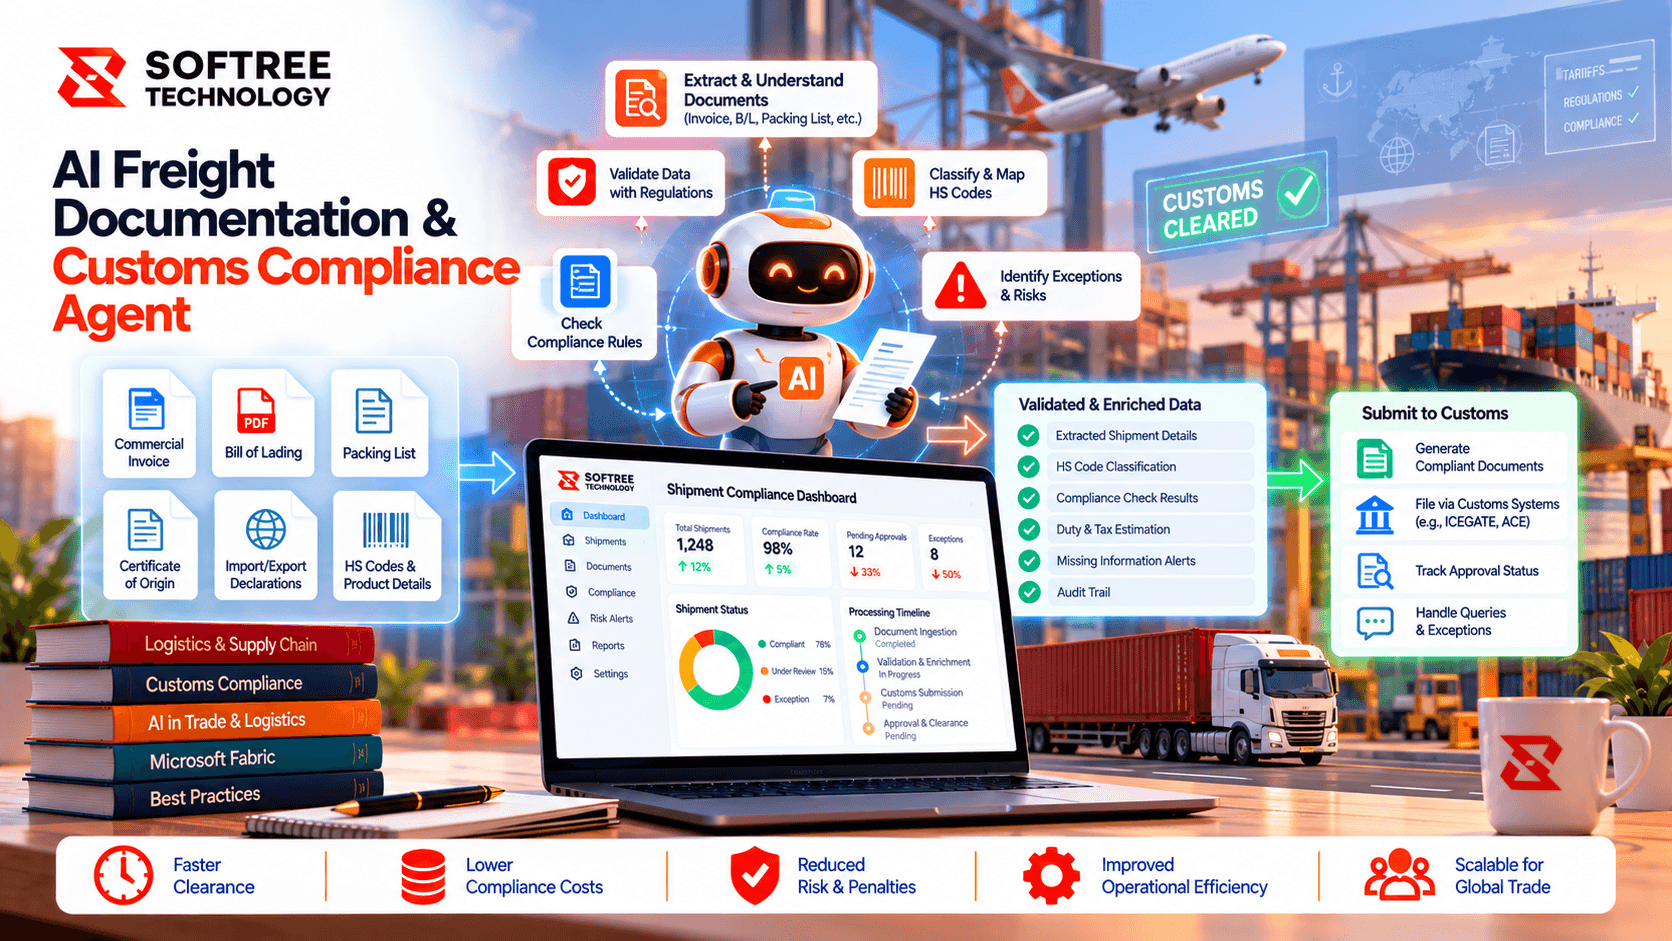
AI Freight Documentation & Customs Compliance Agent
A UAE freight operator used an AI documentation agent to identify shipment gaps, flag discrepancies, and route customs exceptions for review.
Read case study→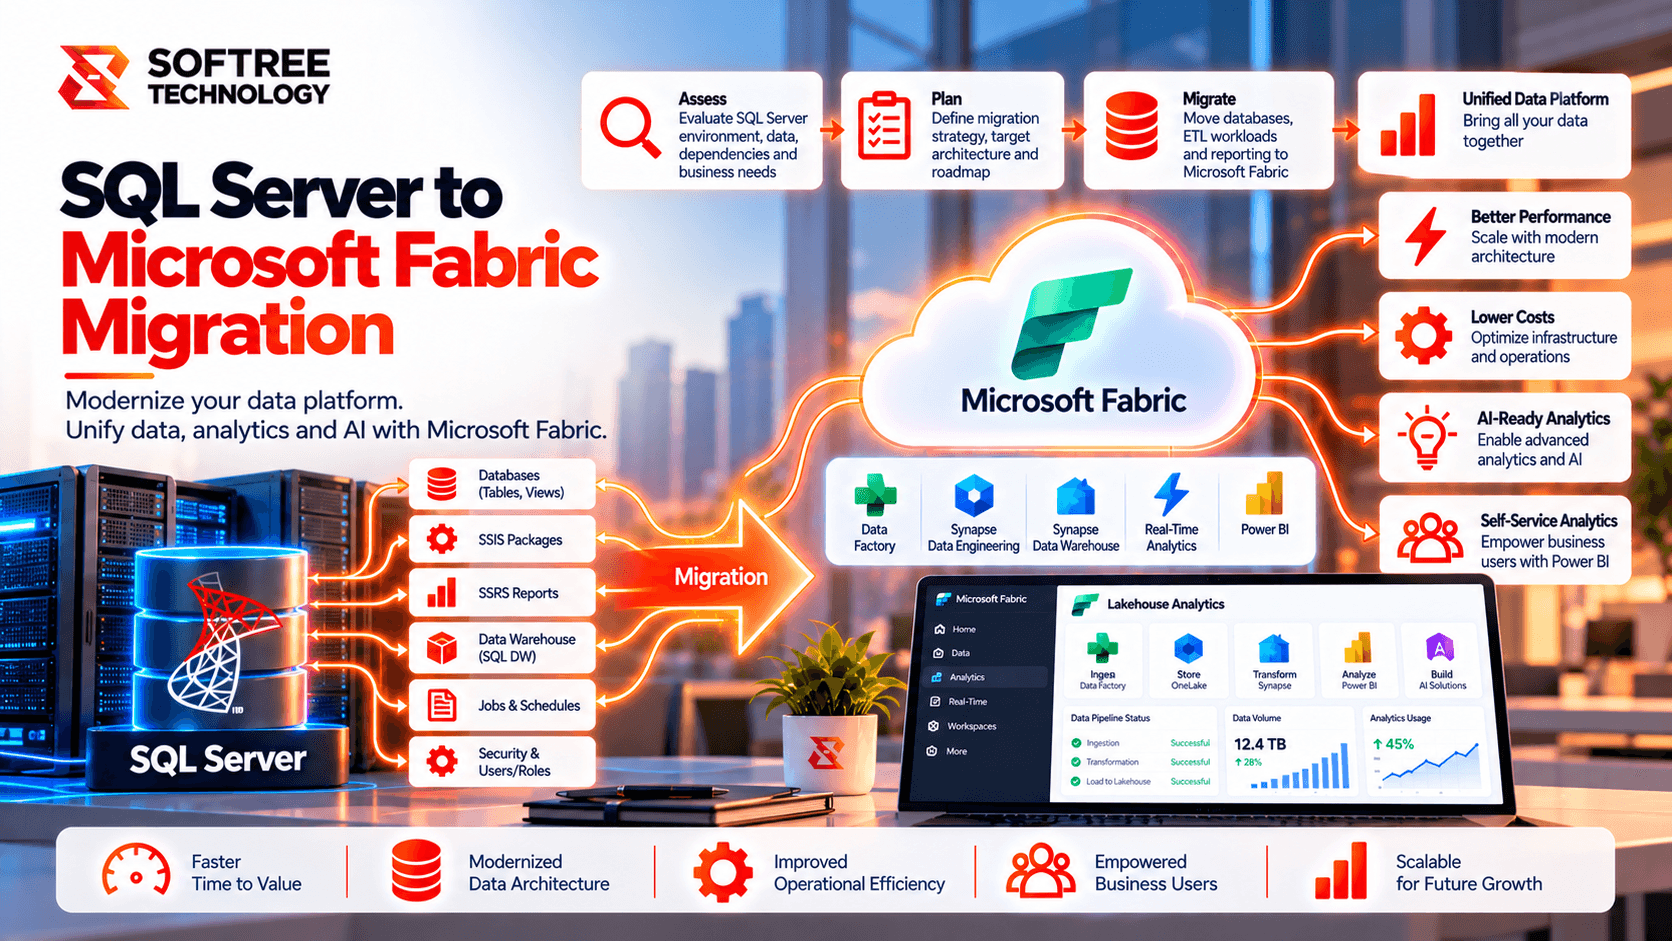
SQL Server to Microsoft Fabric Data Warehouse Migration
Modernizing an enterprise SQL Server data warehouse with Microsoft Fabric while maintaining data quality, performance, security, and reporting continuity.
Read case study→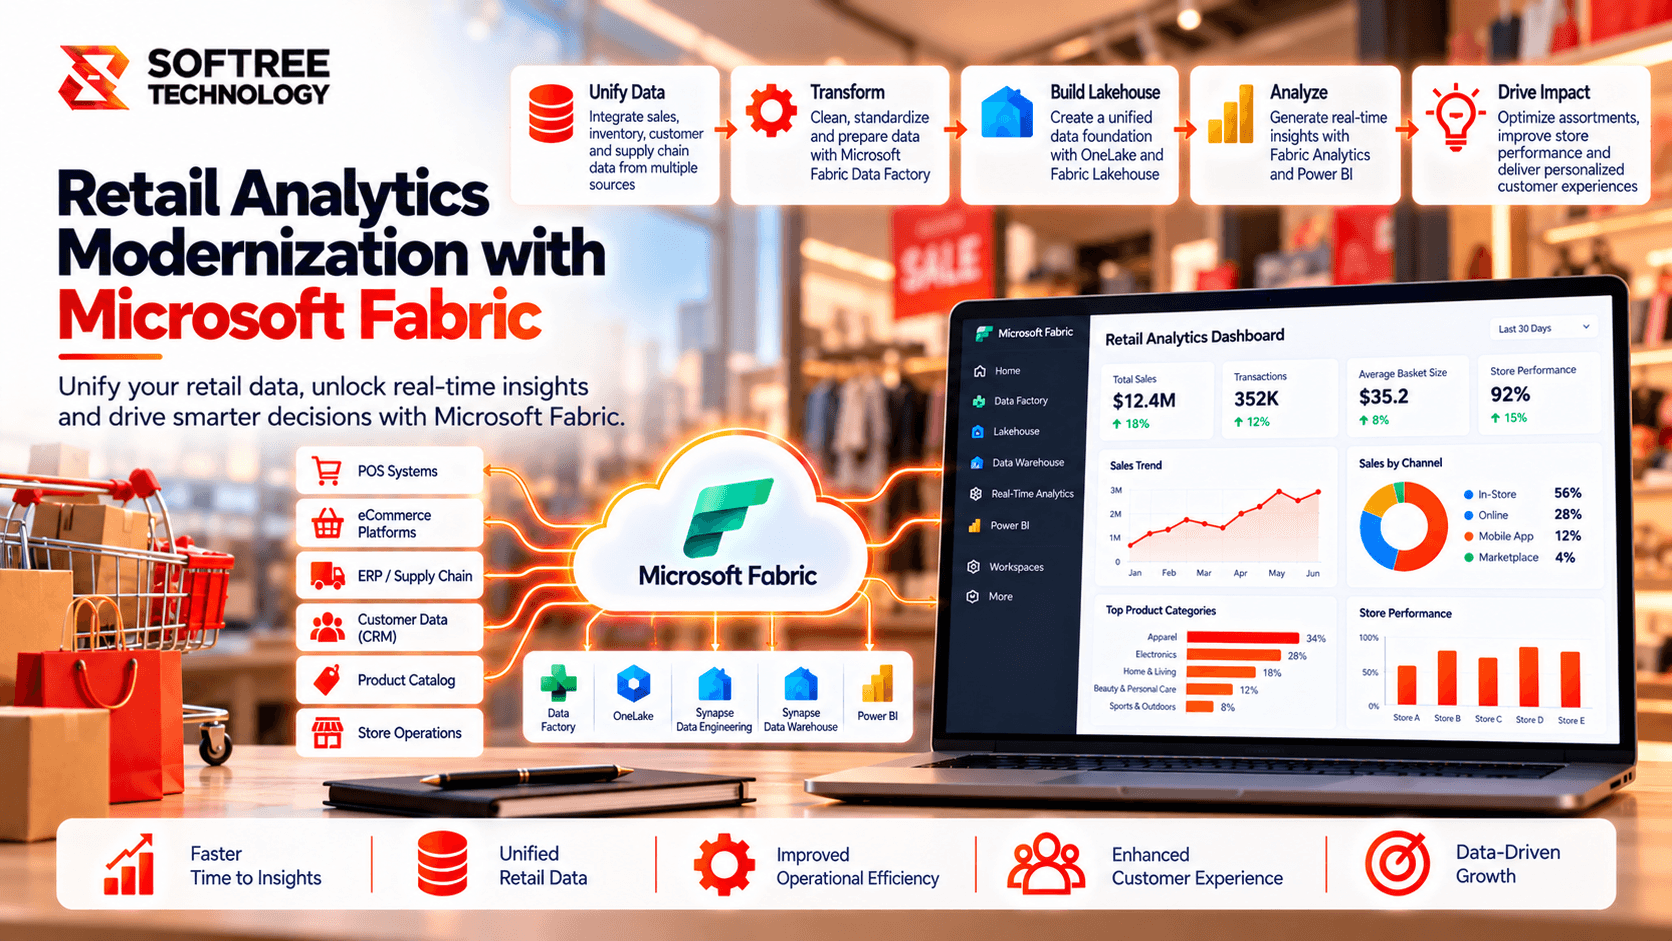
Retail Analytics Modernization with Microsoft Fabric.
Softree modernized a retail analytics environment with Microsoft Fabric, improving data governance, semantic model reuse and Power BI performance.
Read case study→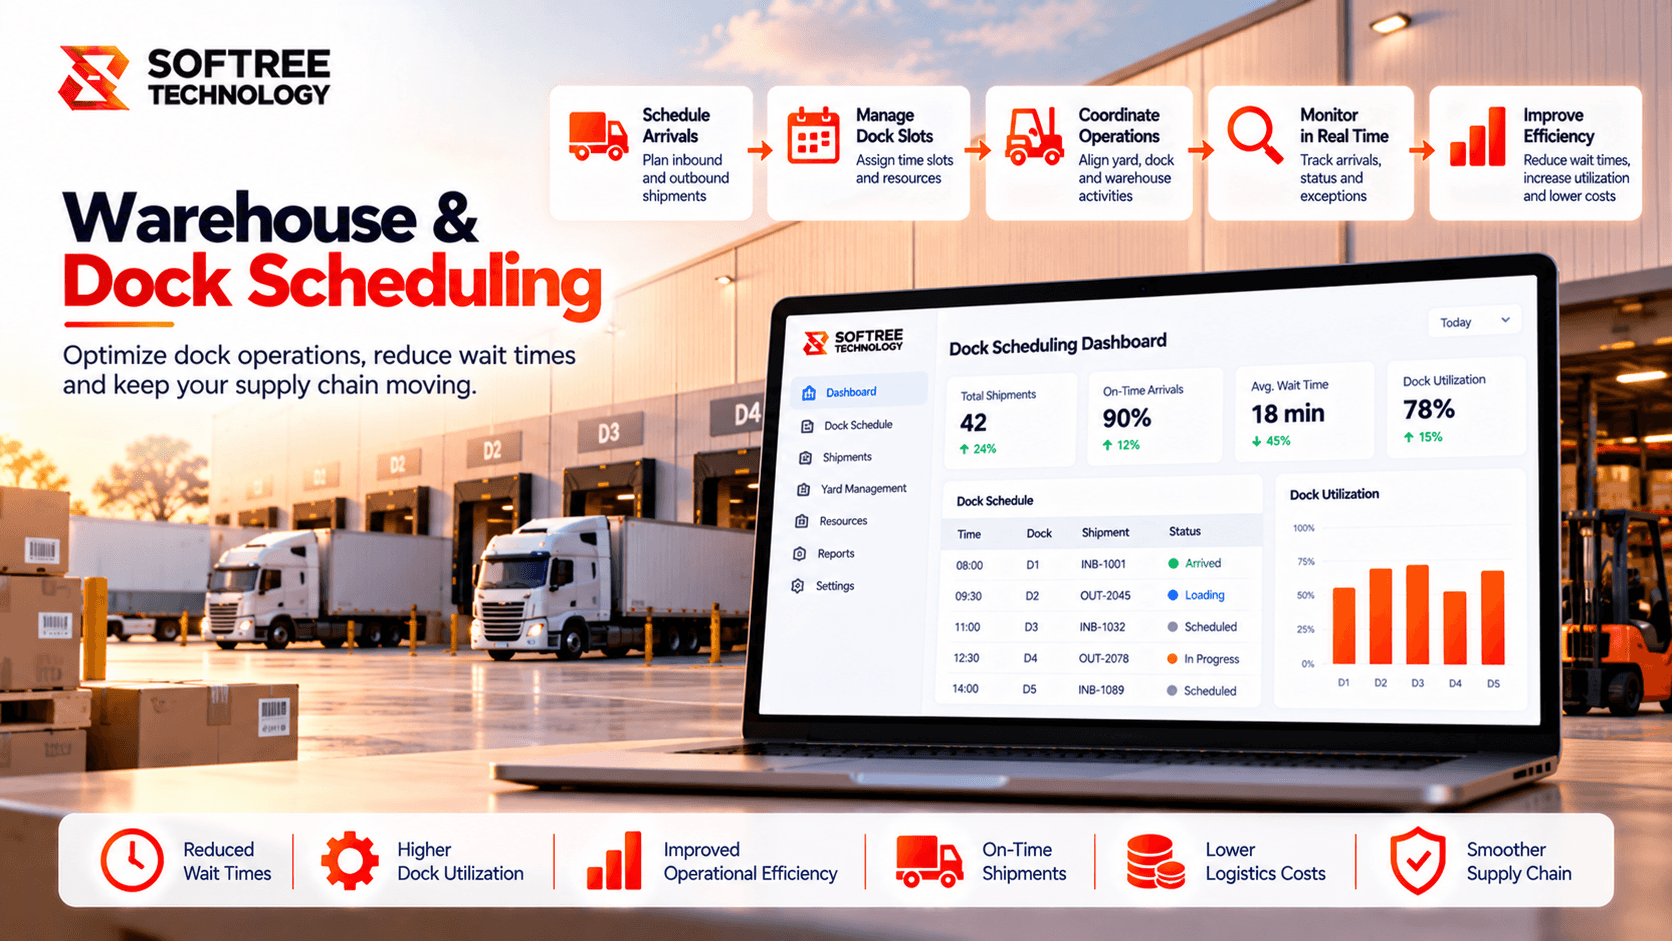
Intelligent AI for Warehouse & Dock Scheduling
An AI-powered scheduling agent to analyze warehouse operations, identify dock conflicts, recommend feasible rescheduling options, and improve coordination across carriers, planners, and warehouse teams.
Read case study→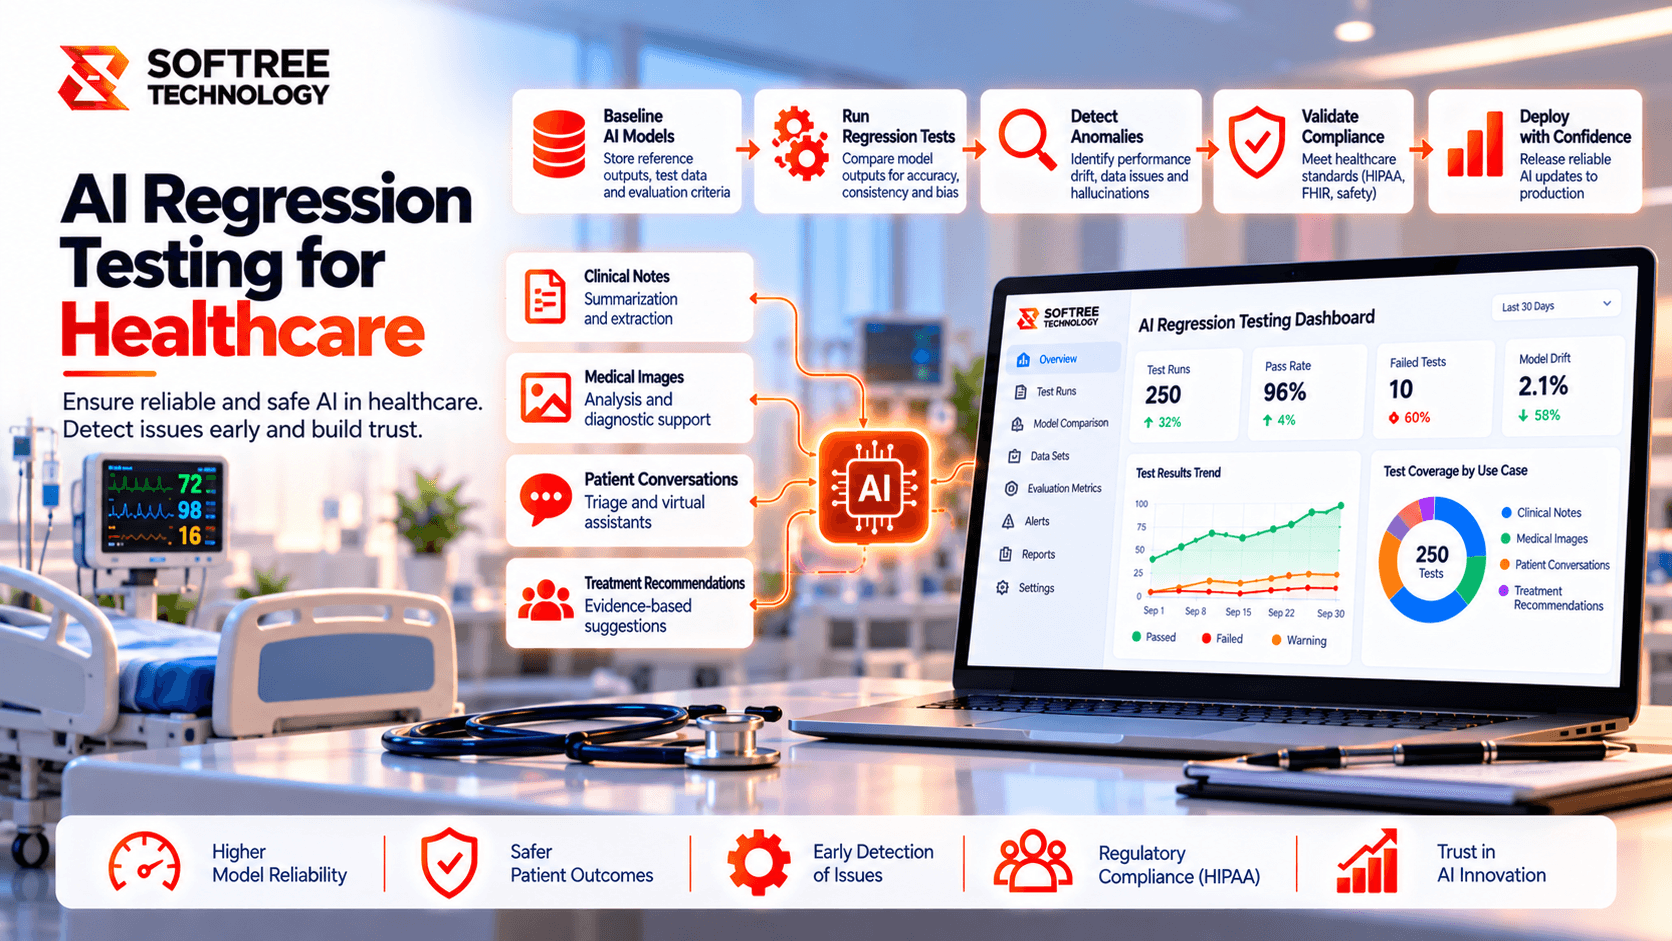
AI Regression Testing for Healthcare Applications
CliniRegress AI uses risk-based test selection to help healthcare QA teams reduce regression effort while protecting critical clinical workflows.
Read case study→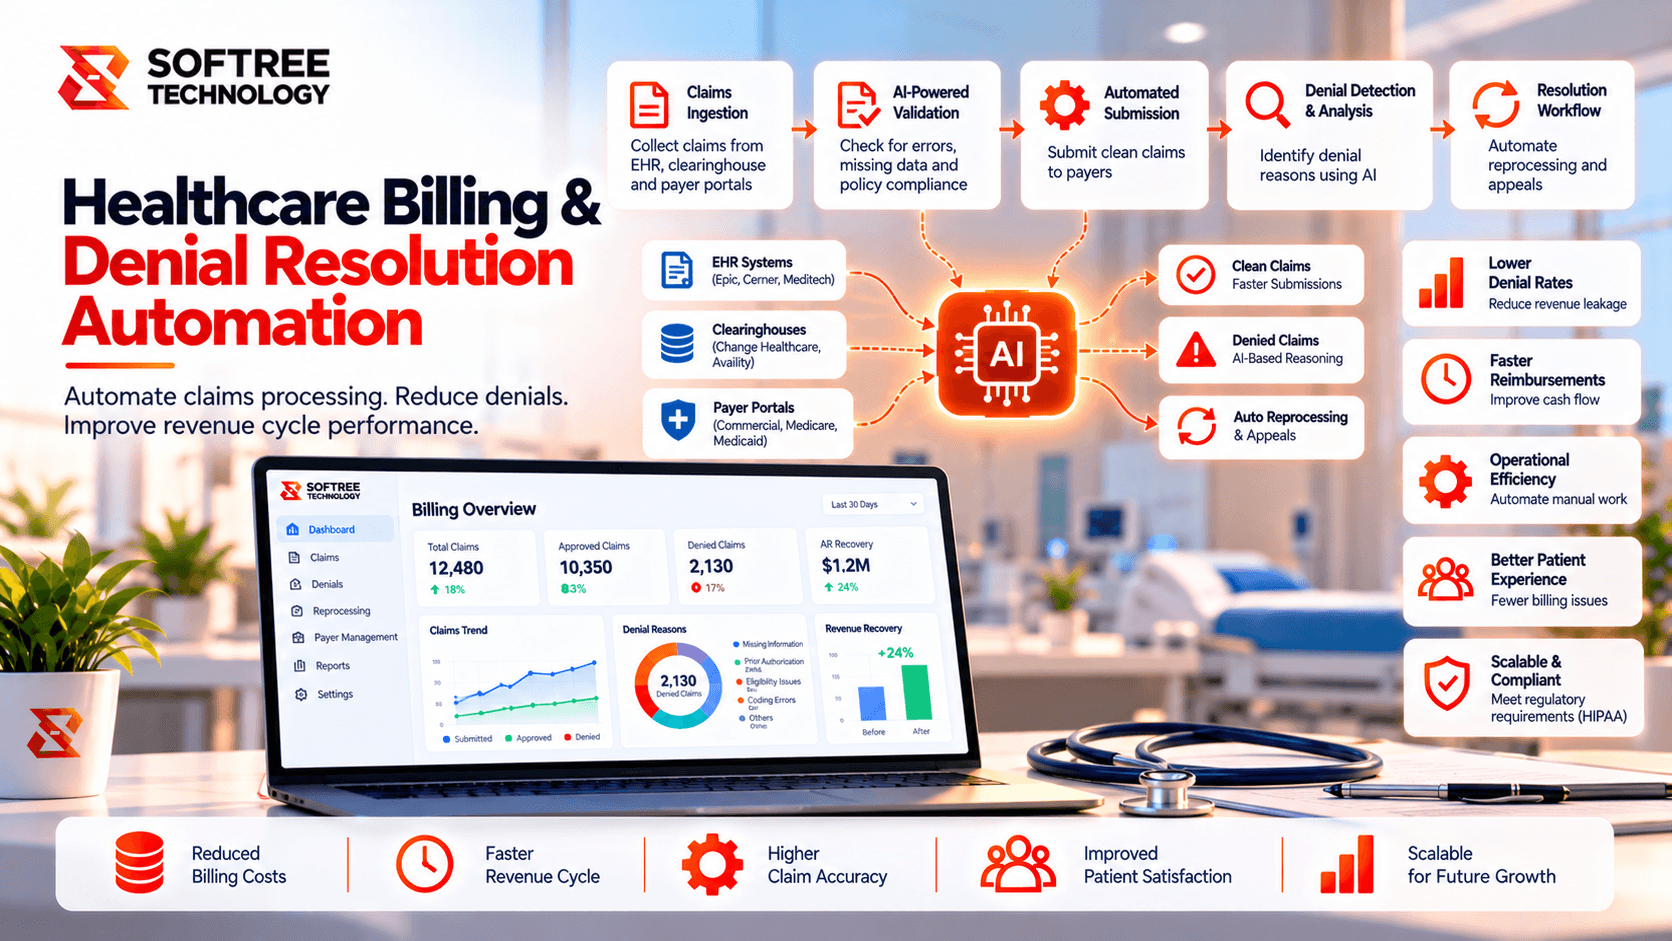
Healthcare Billing & Denial Resolution Agent
A Singapore healthcare provider proposed an AI agent to streamline claim denial investigations, payer research, follow-ups, and specialist review.
Read case study→Frequently asked questions.
Build faster with a reliable offshore engineering partner.
Partner with Softree to accelerate product delivery, modernize enterprise systems, and scale with confidence.
What we offer
Offices
Bengaluru
11th Floor, Prestige Tech Park, Platina 2 · Outer Ring Rd, Kadubeesanahalli · Bengaluru, Karnataka 560087, India
Cuttack
PLOT B6-1628, SECTOR-10, CDA · Cuttack, Odisha 753014 · India
San Francisco
San Francisco, CA 94108 · United States
Got a question, challenge, or idea?
Fill out the form or pick a time on our scheduler.
30-min discovery call
Same Calendly as our booking page · instant invite